
Introduction Artificial Intelligence is changing how organizations operate, but choosing the right AI model can be confusing. Recently, applications like AI agents and large language models (LLMs) have gained massive popularity. However, as models grow to hundreds of billions or even trillions of parameters, the demand for computing power and memory has reached record highs . To solve these hardware and cost constraints, researchers began focusing on methods to reduce the compute resources needed to train, store, and run AI models. This effort led to the rise of Small Language Models (SLMs). The growing potential of these compact models was highlighted in a research paper by Nvidia titled Small Language Models are the Future of Agentic AI One of its main conclusions aligns directly with practical enterprise needs: since AI agents are typically built to handle very specific tasks, businesses do not always need a massive, hundred-billion-parameter LLM to get the job done efficiently. It is important to understand that SLMs are not meant to completely replace LLMs. Instead, they were created to address specific challenges, such as lowering infrastructure costs, speeding up response times, and providing better data privacy. In this article, we will explore both LLMs and SLMs, see what makes small models stand out, and help you choose the best option for your company or upcoming project. What is a Large Language Model (LLM)? A Large Language Model (LLM) is a massive AI system trained on broad, internet-scale datasets (such as books, Wikipedia, and GitHub). It is designed to handle wide domain knowledge, open-ended creativity, and multi-step reasoning. Examples of LLMs are GPT-5, Claude Opus 4.6, Llama 4 Scout, DeepSeek V4-Pro, and Mistral Large 3. Read Also: From Hallucination to Precision: How Data Collection and Annotation Fix LLM Errors What is a Small Language Model (SLM)? A Small Language Model (SLM) is a compact model (typically under 10 billion parameters) designed to run efficiently on fewer computational resources. SLMs prove that high-quality, filtered, or synthetic training data can beat raw data volume on structured reasoning tasks. Examples of SLMs in real life are Phi-3-mini (3.8B), Phi-4 (14B), Mistral 7B, Gemma 3 (4B), and Command R7B. What determines whether the Language Model is Large or Small? SLMs have fewer parameters and are trained on specific company’s data, while LLMs are trained on massive data sets from different sources, but these are not the only differences. LLMs and SLMs differ in many ways: Category Small Language Models (SLMs) Large Language Models (LLMs) Parameters 1B to 10B parameters 70B to 1T+ parameters Hardware Single consumer GPU, laptop, or edge device Multi-GPU servers (e.g., A100 or H100) Inference Latency Tens of milliseconds Hundreds of milliseconds (cloud-hosted) Cost per 1M Tokens ~$0.02 to $0.20 ~$1.25 to $15 Fine-Tuning Time Hours on a single GPU Days to weeks on a cluster Deployment On-device, on-premise, edge, or cloud Primarily cloud APIs Data Privacy Strong (local/on-premise deployment is viable) Data leaves your network by default Read Also: Building Trust in LLM Answers: Highlighting Source Texts in PDFs What Makes Small Language Models SLMs Stand Out? Small Language Models offer key features that make them effective for businesses operating under strict compliance, data privacy, or budget limits, SLMs offer unmatched advantages, like: 1. Custom Fine Tuning on Internal Data Small models can be trained directly on a company’s private documents, such as medical records or customer support logs. Techniques like Parameter Efficient Fine Tuning allow a small model to learn new domain knowledge on a single graphics card in just a few hours. Once adapted to a specific topic, a small model can perform narrow tasks with accuracy that matches large general models. However, the success of any fine-tuning depends entirely on data quality. Before training your model, you need structured Data Collection and precise Data Annotation to ensure the model learns from accurate, clean, and relevant internal records 2. Data Privacy & Compliance Data privacy depends entirely on how the model is deployed. If you access a model through a third party cloud API, your data leaves your internal network by default and travels to external servers. However, when you download an open source Small Language Model and host it locally on your company’s own servers, your sensitive information never touches the internet. Because no data is transmitted back to the original creators of the model, your company maintains full compliance with strict privacy regulations. Technical Expertise Required Large models are often ready to use right out of the box. Small models, on the other hand, require deeper data science skills and clear domain knowledge to properly customize and fine-tune them for your specific business. 4. Managing Model Bias Because small models train on limited datasets, controlling bias is generally easier. However, if the underlying training data lacks balance, the model can still show linguistic or regional biases. When to Use LLMs and When to Use SLMs Neither model type is inherently better than the other. The best choice depends on your specific goals, your budget, whether data privacy is a priority, and the overall complexity of the work you need to perform. When to Use a Large Language Model (LLM) You need to solve complex tasks that require multiple steps of logic, such as updating software code or analyzing legal documents. You need to handle completely new or unclear prompts where no previous training examples are available. You need to create creative content, write stories, or brainstorm ideas across broad subject areas. You need to read and analyze massive single documents or large software codebases that require broad memory windows. When to Use a Small Language Model (SLM) You need absolute data protection and must keep sensitive records on your own local servers. You need immediate response times for fast interaction with users. You need to handle high volumes of repetitive daily work like sorting documents, routing emails, or summarizing text at low operational cost. You need fast and low cost subtasks to support automated pipeline agents. Connecting Multiple Small Models A smart

Introduction Visual AI is moving beyond simple object detection and image classification. Today, AI systems are expected to understand visual information, make decisions, interact with other tools, and complete tasks with minimal human intervention. This shift is creating demand for more flexible and intelligent visual AI workflows. Instead of building every component separately, developers and businesses need ways to connect computer vision models with reasoning, automation, data processing, and external tools. This is where Ultralytics Agents come into play. By combining computer vision capabilities with agent-based workflows, Ultralytics Agents provide a way to build visual AI applications that can analyze information, take actions, and automate complex processes more efficiently. What Are Ultralytics Agents? Ultralytics is widely known for its YOLO family of computer vision models, which are used for tasks such as object detection, image segmentation, pose estimation, classification, and tracking. Ultralytics Agents extend this vision-focused ecosystem toward AI workflows where models can do more than simply return predictions. An AI agent can be designed to: Understand a task or objective Analyze visual information Use computer vision models Process model outputs Interact with tools or applications Make decisions based on predefined workflows Trigger actions automatically Work through multi-step processes This creates a bridge between computer vision and intelligent automation. For example, rather than simply detecting a vehicle in an image, a visual AI workflow could identify the vehicle, determine its location, track it across multiple frames, analyze additional information, and trigger an action based on the result. Why Visual AI Workflows Are Becoming More Complex Traditional computer vision applications often follow a relatively straightforward pipeline: Input → Model → Prediction → Output For many applications, this approach works well. But real-world AI systems frequently require additional steps. Consider a warehouse monitoring application. A model might detect workers, forklifts, packages, and restricted areas. However, detection alone may not be enough. A complete workflow might need to: Detects objects in a video stream. Track objects across frames. Determine whether a person has entered a restricted area. Check the duration of the event. Record relevant information. Notify an operator. Store the event for later analysis. The computer vision model is only one part of the overall system. This is why modern visual AI applications increasingly require workflows rather than standalone models. From Computer Vision Models to AI Agents AI agents introduce another layer of intelligence around models. Instead of treating a computer vision model as an isolated component, an agent-based workflow can use model outputs as part of a broader decision-making process. For example: Camera Feed → Vision Model → Agent → Decision → Action The vision model provides information about what is happening. The agent can then use that information within a workflow to determine what should happen next. This architecture can be particularly useful when applications involve multiple steps, tools, or conditions. Example: Automated Safety Monitoring Imagine an industrial facility where cameras monitor work areas. A visual AI workflow could detect: Workers Safety equipment Vehicles Restricted zones Potential hazards The agent could then evaluate the detected information against predefined rules. If a worker enters a restricted area without the required safety equipment, the workflow could: Create an incident record Capture relevant evidence Notify the appropriate team Assign a priority Store the event for further review Instead of requiring a human to continuously monitor every camera, the system can automate parts of the monitoring process. Key Benefits of Agent-Based Visual AI 1. Faster Workflow Development Building a sophisticated AI application from scratch can require significant engineering effort. Developers may need to integrate: Computer vision models APIs Databases Business logic Automation tools Monitoring systems Notification services Agent-based approaches can simplify how these components are connected, helping teams move from an idea to a functional workflow more quickly. 2. Multi-Step Automation Many visual AI applications are not single-step problems. An agent can help coordinate multiple operations within the same workflow. For example: Detect → Analyze → Verify → Decide → Act This can reduce the amount of manual orchestration required between individual components. 3. Better Use of Visual Data Organizations generate enormous amounts of visual information through cameras, inspections, medical imaging, autonomous vehicles, retail systems, and other applications. The challenge is not simply collecting this data. It is turning it into useful information and actions. Visual AI workflows can help organizations move from: Raw visual data → Insights → Decisions → Actions 4. Flexible Integration Real-world applications rarely operate in isolation. A visual AI workflow may need to communicate with databases, APIs, dashboards, alerting systems, or internal business applications. An agent-based architecture can provide a flexible layer for connecting these different components. 5. Human-in-the-Loop Workflows Automation does not always mean removing humans from the process. For sensitive or complex applications, AI can identify relevant cases and send them to human experts for review. For example: AI detects → AI evaluates → Human verifies → System records result This approach can be valuable when accuracy, compliance, or safety is critical. Use Cases for Ultralytics Agents The combination of computer vision and agent-based workflows can support a wide range of applications. Autonomous Vehicles Autonomous driving systems process large volumes of visual information from cameras and other sensors. Visual AI workflows can help with tasks such as: Object detection Vehicle and pedestrian tracking Road-scene understanding Traffic monitoring Event detection Data validation Agents can help coordinate these outputs and connect them with downstream systems. Manufacturing Factories can use computer vision to monitor production lines and identify anomalies. Possible workflows include: Product inspection Defect detection Worker safety monitoring Equipment monitoring Inventory tracking Production analytics Instead of simply identifying a defective product, an automated workflow could flag the item, record the defect, notify an operator, and update the relevant production system. Retail Retailers can use visual AI to understand activity inside stores. Applications may include: Customer movement analysis Shelf monitoring Product detection Inventory monitoring Queue analysis Loss prevention An agent can connect visual insights with business systems to support automated responses. Healthcare Medical imaging represents another area where visual
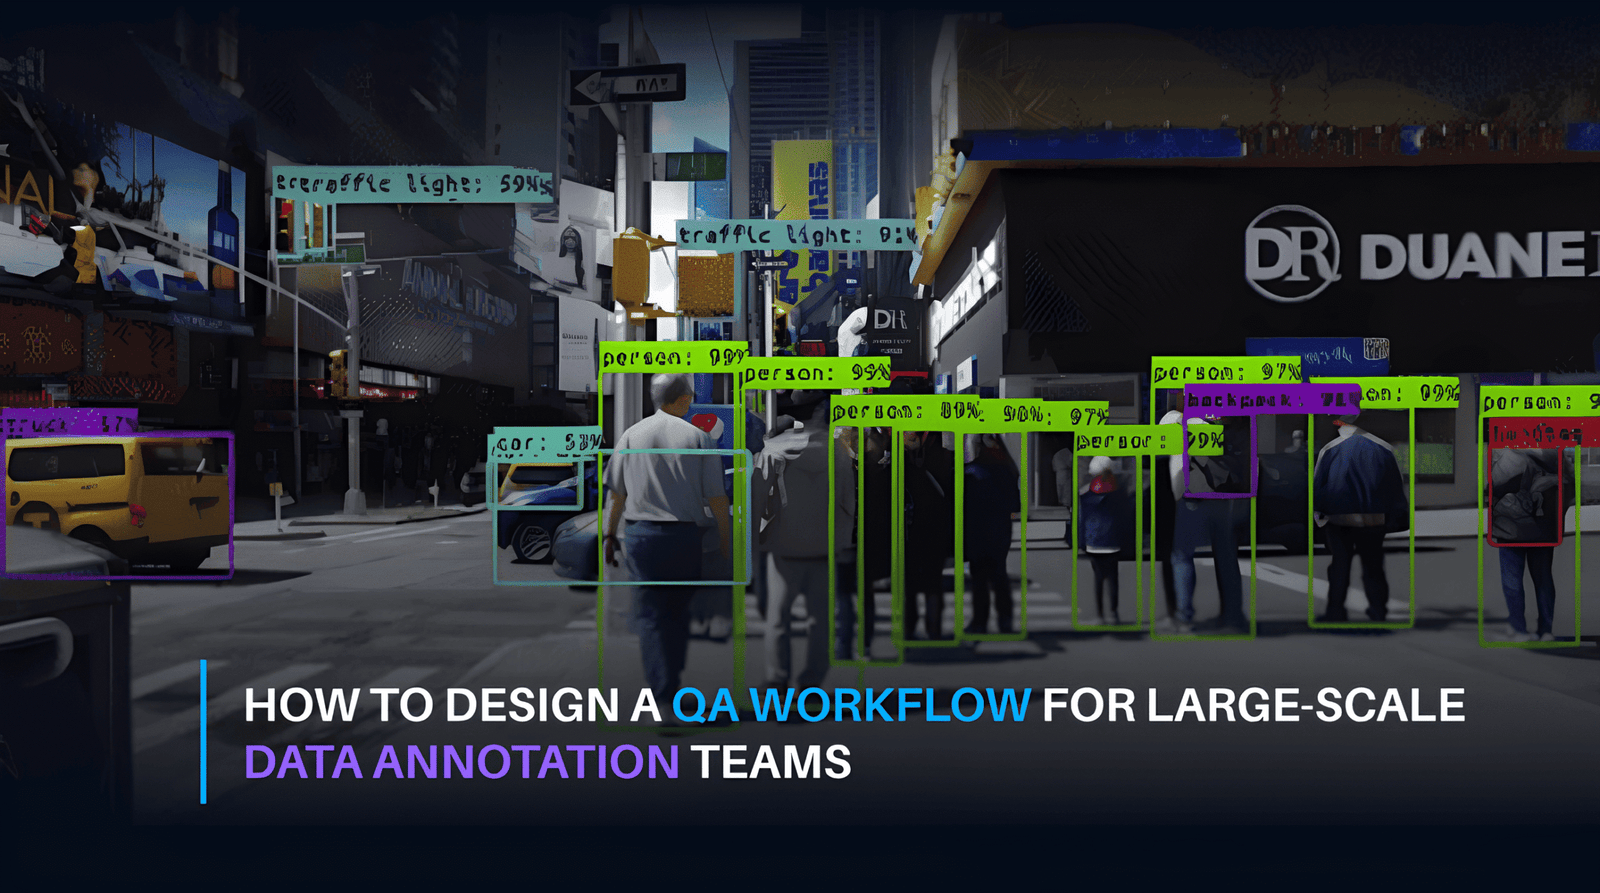
Introduction AI and machine learning systems rely heavily on labeled data. Mastering scaling data annotation operations requires a balance between speed and quality control. Focusing on improving data annotation accuracy is crucial when scaling ML operations. No matter how advanced your algorithms are, training data quality ultimately limits overall performance. Getting high-quality training data training data in early stages or pilot batches is usually manageable. The real challenge starts when you scale up to production volumes. At this stage, most teams struggle with quality loss as data volume increases. This rush to meet tight deadlines causes teams to overlook edge cases. Managing quality is straightforward with a small team of 3 annotators. However, as you scale to 30 or 50 annotators, individual understandings of the guidelines diverge. This leads to inconsistent data that directly degrades model accuracy. During annotation projects, edge cases inevitably emerge that force guidelines to evolve. The core challenge is ensuring every annotator receives and understands updates simultaneously. This prevents half the team from working on outdated rules. Furthermore, labeling is mentally demanding, and handling thousands of repetitive samples causes fatigue, letting small errors slip through and requiring proactive oversight of team well-being. Does scaling mean you have to compromise on accuracy? Not at all. Leading annotation teams show that you can expand data volume while maintaining, and even improving, quality standards. The key is building a workflow and process designed specifically to protect quality as you grow. Maintaining AI training data quality requires strict compliance with workflow guidelines. This article shows how data annotation teams can scale their operations from hundreds to millions of labels without sacrificing accuracy. Defining high-quality training data In data annotation, quality isn’t just about avoiding individual errors; it’s about minimizing annotation overhead, the time, effort, and resources spent to maintain consistency, accuracy, and reliability across your entire dataset. High-quality data ensures that labels remain consistent across different team members and align perfectly with model requirements, directly driving the overall success of AI/ML projects. Read Also: LiDAR Annotation Quality Checklist for Autonomous Vehicles Quality Assurance Workflow Quality assurance shouldn’t happen only after the work is done. Instead, it must be integrated into every stage of the data annotation process. Especially when scaling to large volumes of datasets, building a flexible workflow is essential, Here is how to design a QA workflow that maintains quality at scale: Clear Instructions Before Project Launch Most quality issues stem from unclear instructions at the start. Protecting quality begins with creating a comprehensive guide that covers basic definitions, clear examples, and explicit steps for handling ambiguous cases. Setting measurable standards for acceptable work upfront prevents costly rework later. Organizing Workflow Efficiency Removing administrative and technical bottlenecks boosts your team’s ability to handle larger data volumes. This is achieved by clearly defining responsibilities, using real-time tracking, and applying smart filtering, routing complex cases to human reviewers while letting straightforward entries pass through automatically. Testing Workflows on Small Samples Jumping straight into large-scale annotation is a major risk. A better approach is testing your workflow on small data batches first. These limited samples expose gaps in guidelines and surface tricky edge cases early, allowing you to establish solid quality baselines before committing to full production. Multi-Tier Annotation QA Process Implementing a structured, multi-tier annotation QA process is essential for maintaining high dataset accuracy at scale. By combining automated validation checks with senior reviewer spot-checks and edge-case consensus reviews, teams can eliminate annotation errors before they reach the model training stage. This layered approach ensures consistent quality control without slowing down overall throughput. Continuous Quality Monitoring Delaying data audits until a full batch is finished leads to wasted time and budget. Modern QA systems rely on continuous monitoring through daily sample checks, tracking annotator agreement rates, identifying recurring error patterns, and triggering immediate alerts if quality drops so issues can be resolved right away. Fast Communication and Feedback Loops Connecting annotators directly with reviewers prevents individual mistakes from turning into team-wide issues. Immediate feedback allows annotators to adjust their approach right away while clarifying confusing concepts using real-world examples encountered on the job. Continuous Guideline Updates As datasets grow, unexpected edge cases always emerge. Guidelines and instructions should be treated as living documents that evolve based on issues uncovered during daily reviews. This transforms QA from a static inspection checkpoint into an adaptive environment for continuous learning. Read Also: How to Choose a Data Annotation Partner for Computer Vision Projects? Final Thoughts Managing scaling data annotation efficiently requires shifting from end-of-process checks to an integrated, multi-stage QA workflow. By combining clear instructions, batch validation, automated checks, expert supervision, and real continuous feedback, teams can scale from hundreds to millions of labels while maintaining high accuracy and consistency. We proved this approach by scaling to over 100 specialists through a two week pilot and three tier QA structure, achieving 98.6% precision. Automated tracking cut manual work by 40%, allowing our team to focus on complex edge cases and deliver Level 4 ADAS data with zero critical errors while saving our client weeks of engineering time If you are preparing to scale your data pipeline, we are here to streamline the process. Get in touch with our experts today to see how we can fuel your AI projects with high-quality training data Frequently Asked Questions (FAQ) Q: Why should QA be embedded into the annotation process instead of done at the end? Catching errors early prevents systemic mistakes from multiplying across large datasets and avoids expensive, time-consuming rework. Q: What is the main cause of quality drops when scaling annotation teams? Quality drops mainly stem from ambiguous guidelines, inconsistent interpretations among new annotators, and fatigue caused by high volumes. Q: How do small pilot batches help maintain quality at scale? Pilot batches expose hidden edge cases and guideline gaps early, establishing solid quality baselines before committing to full production. Visit Our Data Collection Service Visit Now
Introduction Most AI failures labeled as hallucinations aren’t random model glitches. Instead, they are direct, predictable outcomes of how tasks were defined, how data was annotated, and what context was provided or missed. When a model produces wrong outputs, we usually blame the algorithm. But in reality, models simply mirror the structure, ambiguity, and gaps hidden in their training data. In short, hallucinations are rarely spontaneous errors, they are signals highlighting flaws in upstream data design. This article explores how high-quality training data directly corrects errors in large language models (LLMs). We will look at systematic, repeatable error patterns that teams can actually identify and fix What are AI Hallucinations? An AI hallucination is when an AI gives you an answer that sounds confident and smart, but the facts are made up or fabricated. The AI isn’t trying to trick you, it creates information that is factually wrong or unsupported by its training data. The AI isn’t trying to deceive, rather than truly understanding reality, generative systems simply predict the next word or pixel based on statistical patterns, filling in knowledge gaps with plausible-sounding falsehoods. This happens across all modalities, a chatbot might invent a non-existent legal case, or an image generator might render a hand with six fingers. Read Also: Google’s New Paper Challenges the Transformer-Only Future of LLMs What causes AI Hallucination? AI hallucinations are rarely random algorithm failures; they are direct symptoms of underlying data problems. When datasets lack clarity, boundaries, or context, models are forced to fill in the missing logic with invented details. The primary data-driven causes include: 1. Poor and Inconsistent Data Annotation When annotation guidelines are vague, human annotators interpret rules differently, leading to conflicting data labels. When a model trains on inconsistent inputs, it fails to learn clear boundaries. As a result, the AI gets confused and creates fabricated details or unpredictable answers to bridge the gaps in its training. 2. Edge-Case Blind Spots Edge cases are rare, unusual, or complex real-world scenarios that are underrepresented in the training data. If a model encounters a situation it hasn’t seen before, it doesn’t always admit it doesn’t know. Instead, it relies on broad pattern matching to guess an answer, leading directly to confident-sounding hallucinations. 3. Missing Context and Incomplete Instructions Models rely on full context to generate accurate responses. If training examples or prompt instructions lack necessary background details, constraints, or clear scope, the system attempts to complete the logical sequence on its own. It effectively fills in the blanks with made-up information to complete the task. 4. Ambiguous Task Definitions When the overall goal of an annotation task is poorly defined from the start, annotators use different rationales to complete the work. This ambiguity embeds subtle logical contradictions into the dataset. The model then learns these conflicting patterns, making its outputs vary wildly from run to run without any clear explanation. How Data Collection & Annotation Prevent AI Hallucinations? To stop models from making up facts, data teams must change how training datasets are built. Instead of just showing the AI correct answers, the data pipeline must actively teach the model its limits, boundaries, and what to ignore. Here are the four key data strategies to eliminate hallucinations during training: Integrating Hard Negatives to Eliminate Overfitting Data pipelines include near-miss examples, inputs that look correct on the surface but are contextually invalid. For example, distinguishing (aspirin-like symptoms) from an actual aspirin prescription. Explicitly labeling these subtle boundaries prevents models from relying on superficial pattern matching and stops false entity extraction. Null-Output Training to Force Honest Boundaries Annotators explicitly label empty contexts, unanswerable questions, and incomplete passages with a (no answer) or (null) response. This directly counters the model’s natural eagerness to guess, giving it clear permission to state (I don’t know) whenever context is missing. Preference Optimization (DPO/RLHF) on Real Failure Pairs Teams collect the model’s actual hallucinated outputs from production and pair them with human-corrected versions (Chosen vs. Rejected). Fine-tuning on these preference sets actively penalizes the statistical biases that cause the model to make up facts, turning historical errors into strict guardrails. Structuring Taxonomies with Explicit Reason Codes Annotators do not merely mark data as right or wrong; they tag invalid items with specific reason codes (e.g., mentioned in family history, not active diagnosis). Standardizing these reason codes eliminates subjective human labeling, removing the contradictory signals that cause model confusion. Read also: Top Data Annotation Companies in 2026 Final Thoughts Reducing AI hallucinations and building high precision models isn’t just about selecting the right algorithm. It is an end-to-end investment in meticulously preparing training data to align with your specific domain and safety requirements. At SO Development, we help you design reliable AI systems by preparing the exact, high-quality datasets needed to power them. From custom Data Collection to high-precision Data Annotation, including negative data labeling, no answer training, and custom data guidelines, we supply the clean, ethically sourced data your LLMs require to stay grounded. Empower your AI with accuracy, reduce hallucinations at the root source, and build models your users can trust. Connect with our AI data experts today to elevate your data pipeline Frequently Asked Questions (FAQ) Q1: What is an AI hallucination in Large Language Models (LLMs)? An AI hallucination occurs when a model generates an output that sounds confident and plausible, but is factually wrong, fabricated, or unsupported by its training data. Q2: Can AI hallucinations be completely eliminated through prompt engineering alone? No. Prompting can reduce error rates, but it cannot fix underlying pattern-matching flaws; true precision requires fixing the model’s knowledge boundaries directly in the training data. Q3: What are (Hard Negatives) in data annotation, and how do they help? Hard negatives are training examples that look nearly correct but are contextually invalid. Labeling them forces the model to learn precise decision boundaries instead of making broad guesses. Q4: How does Null-Output training prevent model errors? Null-output training explicitly exposes the AI to unanswerable questions and empty contexts, teaching the model to
Introduction The integration of artificial intelligence into medicine is rapidly changing how patient care is delivered, monitored, and managed. High-quality data serves as the foundational fuel for machine learning algorithms, enabling breakthroughs in diagnostic tools, automated clinical workflows, and administrative efficiency. According to industry reports from Mordor Intelligence, the global market size for artificial intelligence in healthcare reached over $53 billion in 2026 and continues to grow with expected 36.21% CAGR in 2031. Behind every reliable AI system is a structured network of specialized data collection providers supplying the necessary datasets while strictly adhering to international privacy frameworks such as HIPAA and GDPR. Applications of AI in Healthcare Medical AI relies on precise data collection and annotation to solve real-world clinical and operational challenges. Today’s HealthTech ecosystem utilizes advanced machine learning, natural language processing, and large language models across several primary applications: Unlocking Insights from Clinical TextA vast amount of medical information remains hidden within unstructured sources such as physician notes, clinical narratives, and diagnostic reports. Natural language processing techniques extract critical entities, including medical codes like LOINC, SNOMED CT, and ICD-10, to standardize unstructured medical records. This makes it easier for healthcare systems to uncover hidden health patterns, accelerate drug target discovery, and streamline clinical trial matching. Empowering Doctors and PatientsModern language models function as real-time decision-support assistants for medical professionals. They deliver up-to-date knowledge during consultations and automate repetitive documentation tasks to reduce clinician burnout. Simultaneously, these platforms generate clear, personalized treatment explanations and side-effect profiles tailored to individual patients, improving overall care comprehension. Optimizing Operational WorkflowsBeyond direct patient care, AI systems evaluate insurance claims, historical medical billing, and provider directories. This allows healthcare institutions to detect fraudulent activities early, predict patient readmission risks, reduce claim denial rates, and streamline administrative management. Leading Healthcare Data Providers Choosing the right provider depends on data accuracy, secure integration capabilities, strict regulatory compliance, and scalable pricing models. Below are top companies delivering high-quality healthcare datasets for AI innovation: SO Development OÜ Taking the top position, SO Development OÜ stands out as a premier B2B data partner serving enterprise engineering teams across Europe and the Middle East & North Africa region. With over five years of industry experience and hundreds of completed projects, the company specializes in compliant preparation for medical AI datasets, including electronic health records, genomic information, and complex medical imaging datasets. Through their specialized medical data collection services, their approach combines high-throughput processing with human-in-the-loop expert validation, ensuring maximum precision while maintaining full alignment with GDPR and HIPAA standards. Definitive Healthcare Definitive Healthcare maintains a massive intelligence platform covering thousands of hospitals and millions of medical specialists. The company offers detailed patient pathway tracking and datasets backed by APIs that easily connect to enterprise platforms like Salesforce and Tableau. Change Healthcare Focusing heavily on financial and clinical workflows, Change Healthcare supplies claim data and administrative datasets. Their infrastructure supports standardized communication protocols like FHIR and HL7, helping healthcare organizations minimize billing errors and improve operational efficiency. Google Cloud Healthcare API Google Cloud provides a highly scalable cloud environment tailored for collecting, storing, and handling electronic health records, large-scale imaging, and genomic datasets. Its direct compatibility with machine learning frameworks like TensorFlow makes it a popular choice for HealthTech startups developing deep learning solutions. NTT Data Healthcare NTT Data specializes in data solutions designed for hospitals and insurance entities. Through structured healthcare datasets, the platform helps institutions minimize unnecessary hospital readmissions, manage health risks across populations, and reduce overall operational costs. NextGen Healthcare Analytics Targeted primarily at outpatient facilities and medical practices, NextGen offers tools that integrate directly into clinical health record software. It allows providers to manage key clinical and operational metrics in real time. Honey Health An AI-driven automation platform that retrieves unstructured medical records directly from unconnected portals. Using AI agents, it securely fetches missing clinical data from independent specialists and labs straight into a practice’s electronic health records. Particle Health A powerful API platform that transforms raw medical records into actionable clinical insights using machine learning. It gives developers secure access to hundreds of millions of patient records aggregated from large healthcare networks. Health Gorilla A federally designated data network that securely accesses and organizes patient records nationwide. It provides the essential infrastructure and APIs needed to power AI-driven healthcare solutions across interconnected health systems. Zus Health A shared health data platform that uses intelligent normalization to create a unified patient history. It cleans up scattered, overlapping clinical records so care teams can view one coherent, standardized profile. Final Thoughts Precise data annotation and reliable medical data collection remain essential pillars for building effective artificial intelligence applications in medicine. As algorithms become more specialized and clinical environments demand greater model safety, having access to secure, high-precision datasets is paramount. Contact Our experts today to help you find the right data for your medical AI project and support your team in scaling your healthcare solution effectively. Visit Our Data Collection Service Visit Now
Introduction Computer vision continues to move toward models that are not only more accurate, but also faster, easier to deploy, and capable of handling multiple vision tasks through a unified framework. In 2026, one of the most important developments in the Ultralytics ecosystem is YOLO26, the latest Ultralytics YOLO model family. Released in January 2026, YOLO26 introduces native end-to-end inference, a lighter detection head, updated training techniques, and support for a broad range of computer vision tasks. For organizations building AI-powered products, YOLO26 is particularly interesting because it targets an important challenge in production computer vision: how to achieve strong accuracy without making deployment unnecessarily complex or computationally expensive. This guide explains everything you need to know about Ultralytics YOLO Vision in 2026, with a particular focus on YOLO26, its architecture, capabilities, performance, training workflow, deployment options, use cases, and differences from YOLO11. What Is Ultralytics YOLO? YOLO stands for You Only Look Once and refers to a family of real-time computer vision models designed to process visual information efficiently. Unlike traditional computer vision pipelines that may require multiple stages to identify and localize objects, YOLO approaches object detection as a unified prediction problem. Over the years, the YOLO ecosystem has expanded beyond basic object detection. Modern Ultralytics models can support: Object detection Instance segmentation Semantic segmentation Image classification Pose estimation Oriented bounding box detection Depth estimation Tracking Open-vocabulary detection and segmentation Ultralytics provides these capabilities through a common Python package and command-line interface, making it easier for developers and machine learning teams to train, evaluate, deploy, and manage vision models. What Is YOLO26? YOLO26 is the latest Ultralytics YOLO model family released in January 2026. It is designed around four major areas of improvement: Native end-to-end inference A lighter detection head A new training recipe Task-specific improvements for different computer vision problems One of its most significant changes is that YOLO26 uses a one-to-one detection head by default, allowing the model to produce final detections without traditional Non-Maximum Suppression (NMS) as a separate post-processing step. This is important because NMS has traditionally been a separate stage in object detection pipelines. Removing it from the default inference path can simplify deployment and reduce post-processing overhead. Read: YOLO26: The Next Evolution of Real-Time Computer Vision Why YOLO26 Matters in 2026 The evolution of computer vision is increasingly focused on practical deployment rather than benchmark performance alone. A model may have excellent accuracy but still be difficult to use in a production environment if it: Requires expensive hardware Has high inference latency Needs complicated post-processing Is difficult to export Performs poorly on edge devices Requires separate models for different vision tasks YOLO26 addresses several of these challenges. According to Ultralytics’ published benchmarks, YOLO26 detection models range from 40.9 to 57.5 mAP on COCO, depending on model size, with reported T4 TensorRT latency from approximately 1.7 ms to 11.8 ms. The smallest YOLO26n model also has a reported CPU ONNX inference speed of 38.9 ms, compared with 56.1 ms for YOLO11n under the documented benchmark conditions. Ultralytics reports up to 43% faster CPU ONNX inference for YOLO26n compared with YOLO11n on an Intel Xeon CPU under its benchmark setup. Key Features of YOLO26 1. Native End-to-End Inference One of the biggest changes in YOLO26 is its native end-to-end detection architecture. Traditional object detection models can produce many overlapping predictions. NMS is then applied to remove redundant predictions and select the final detections. YOLO26’s default one-to-one detection head is designed to produce final predictions directly, eliminating the need for external NMS during standard inference. This can provide several advantages: Simpler inference pipelines Reduced post-processing Easier deployment More predictable execution across platforms Lower latency For edge AI applications, these improvements can be particularly valuable. 2. DFL-Free Regression YOLO26 removes Distribution Focal Loss (DFL) from its detection head. The objective is to simplify the detection architecture while maintaining an effective approach to bounding-box regression. A simpler detection head can also make model export and deployment easier, particularly when targeting environments with strict computational or graph-compatibility requirements. 3. MuSGD Optimizer YOLO26 introduces MuSGD, a hybrid optimization approach combining ideas from SGD and Muon-style optimization. The official training recipe uses MuSGD for the YOLO26 checkpoints trained on COCO. Ultralytics reports that the models were trained at 640×640 resolution with a batch size of 128. This illustrates an important direction in modern AI development: optimization techniques originally associated with other deep-learning workloads are increasingly being adapted for computer vision. 4. Progressive Loss YOLO26 uses Progressive Loss to better align training with the model’s inference-time behavior. The objective is to focus training more effectively on the prediction head that will actually be used during deployment. This can help reduce the mismatch between how a model is optimized during training and how it operates during real-world inference. 5. Small-Target-Aware Label Assignment Detecting small objects is a common challenge in computer vision. YOLO26 introduces Small-Target-Aware Label Assignment (STAL) to improve positive label coverage for small objects. This can be particularly relevant for applications involving: Traffic cameras Drone imagery Surveillance Satellite imagery Manufacturing inspection Retail analytics Small objects often occupy only a tiny percentage of an image, making them difficult to detect reliably. YOLO26 Model Sizes YOLO26 is available in five primary detection sizes: Model Parameters FLOPs COCO mAP CPU ONNX T4 TensorRT YOLO26n 2.4M 5.4B 40.9 38.9 ms 1.7 ms YOLO26s 9.5M 20.7B 48.6 87.2 ms 2.5 ms YOLO26m 20.4M 68.2B 53.1 220.0 ms 4.7 ms YOLO26l 24.8M 86.4B 55.0 286.2 ms 6.2 ms YOLO26x 55.7M 193.9B 57.5 525.8 ms 11.8 ms The figures above are Ultralytics’ published benchmark results and should be treated as reference measurements rather than guarantees for every hardware configuration. Which YOLO26 model should you choose? YOLO26n: Best when low compute, small model size, and edge deployment are priorities. YOLO26s: A strong choice when you need a balance between efficiency and accuracy. YOLO26m: Suitable for applications where additional accuracy is worth increased compute. YOLO26l: Designed for demanding workloads requiring higher accuracy. YOLO26x: Best suited to scenarios where
Introduction The rapid acceleration of artificial intelligence relies on a critical foundation: massive volumes of high-quality data. According to Grand View Research, the global data collection and labeling market reached a valuation of $3.8 billion in 2024. Driven by the rising demand for high-grade datasets to train machine learning and AI systems, this market is projected to expand from $6.3 billion in 2026 to $17.1 billion by 2030, reflecting a compound annual growth rate (CAGR) of 28.4% between 2025 and 2030. North America led the sector in 2024, holding a 35.0% revenue share. Why AI Teams Rely on Specialized Data Collection Providers Data collection companies are specialized partners that gather, structure, refine, and label datasets specifically built for ML/AI. They convert raw, fragmented information into cleanly annotated inputs that AI algorithms require for effective learning. While in-house data gathering might seem straightforward initially, internal teams quickly face bottlenecks. In-house pipelines often lack global demographic reach, specialized domain expertise, and automated validation workflows. The performance of any AI model is directly bounded by the quality of its training data feeding poor or biased data into a model that yields unreliable outputs. Partnering with dedicated providers grants access to established data pipelines, strict quality controls, human-in-the-loop (HITL) verification, and ethical sourcing standards. Top 10 AI Data Collection Companies in 2026 SO Development OÜ Best for Managed B2B AI Data Solutions (EU & MENA) SO Development stands out as the premier partner for enterprise engineering teams across Europe and the MENA region. Bringing over 5 years of domain experience, 600+ completed projects across 25+ countries, and a dedicated network of 600+ skilled specialists, the company provides end-to-end data gathering and labeling pipelines. They combine high-throughput tooling with rigorous Human-in-the-Loop (HITL) validation to guarantee top-tier accuracy. SO Development provides complete end-to-end AI data solutions, including data collection and data annotation. Our primary data collection services include: Video & Image Data Collection: Curating static visual datasets and temporal video sequences for computer vision, object detection, and action recognition across e-commerce and autonomous systems. Audio & Speech Data Collection: Gathering diverse speech patterns, accents, and environmental acoustics for voice assistants, acoustic analysis, and conversational AI. Text Data Collection: Building nuanced multilingual text resources, localized Arabic datasets, and domain-specific text for NLP tasks like sentiment analysis and LLM tuning. Medical Data Collection: Managing sensitive healthcare datasets including diagnostic imaging (MRIs, CT scans, X-rays), EHR records, and wearable monitoring data under strict privacy standards. Off-The-Shelf Datasets: Offering direct access to pre-organized, ready-to-use data libraries spanning video, text, medical, image, and audio formats to speed up model prototyping. Key Capabilities Specialty Compliance & Security SLAs & Support 600+ workforce, multi-modal collection, HITL validation Medical AI, Arabic/Multilingual NLP, Autonomous Vision GDPR aligned, HIPAA compliant frameworks Enterprise custom SLAs, rapid delivery options Also Read: Top Data Annotation Companies in 2026 Scale AI Founded in 2016 in San Francisco, Scale AI delivers enterprise-grade data platforms with strong capabilities in 3D sensor fusion and LiDAR processing. They hold high-level defense contracts and serve major global tech enterprises. They excel in 3D sensor fusion, LiDAR processing, and AI-assisted labeling through platforms like Scale Nucleus and Scale Rapid, backed by a hybrid workforce of 240K+ contractors with ML-powered quality control. Scale AI holds high-level government security clearances and defense contracts, serving Fortune 500 enterprises, government initiatives, and autonomous vehicle programs with enterprise custom SLAs and 24/7 dedicated support tiers. Appen Operating since 1996 from Sydney, Appen offers extensive international reach with wide crowd contributors across 170+ countries and 180+ languages. Powered by their proprietary Appen Connect platform, they specialize in large-scale search relevance evaluation, speech recognition, and advanced generative AI capabilities like RLHF (Reinforcement Learning from Human Feedback). They support global enterprises, LLM projects, and recommendation engines through project-based SLAs and dedicated enterprise program managers. Unidata.pro Unidata.pro is a primary provider of biometric training data, offering specialized datasets for face recognition, liveness verification, and Presentation Attack Detection (PAD). Operating a proprietary collection platform with in-house professional collectors, Unidata.pro provides comprehensive demographic coverage and iBeta/FIDO certification-ready datasets. Their presentation attack datasets cover 2D prints, 3D silicone masks, and deepfake scenarios for financial services, mobile authentication, border security, and identity verification platforms under custom SLAs and rapid delivery options. TELUS International Leveraging its strategic acquisition of Lionbridge AI, TELUS International stands as one of the best AI data collection companies in 2026 for complex natural language processing applications. Supporting 50+ languages with native-speaker annotators, the company specializes in high-context tasks such as sentiment analysis, intent classification, content moderation, and conversational AI training. Backed by robust TELUS enterprise infrastructure and established compliance frameworks (HIPAA, GDPR), they deliver enterprise SLAs tailored to multinational corporations, e-commerce platforms, and healthcare NLP initiatives Shaip Shaip offers specialized healthcare AI training data, delivering HIPAA-compliant collection and annotation pipelines designed for life sciences applications. Operating on the ShaipCloud platform, their workforce includes medical professionals capable of annotating complex radiology, pathology, and clinical NLP datasets. Shaip serves pharmaceutical companies, medical device manufacturers, and clinical decision support developers with HIPAA-compliant SLAs and available Business Associate Agreements (BAA). Sama Sama operates as a certified B Corporation focused on ethical data practices. Providing living-wage employment across East Africa, Sama maintains high accuracy through an in-house trained workforce. Sama delivers computer vision, image, and video annotation services with documented accuracy exceeding 95%. Their approach offers transparent ethical sourcing and ESG reporting support, backed by quality guarantee SLAs for organizations prioritizing ethical AI development in automotive and retail sectors. Defined.ai Defined.ai operates a structured data marketplace connecting AI developers with speech and audio datasets, specializing in regional dialects and underrepresented languages. Defined focuses heavily on low-resource languages and dialect diversity, offering both off-the-shelf audio datasets and custom collection services. Designed for voice assistant developers, speech recognition platforms, and conversational AI teams, Defined.ai provides flexible marketplace terms alongside custom enterprise agreements. Centific Centific delivers industry-specific data pipelines focused on retail and financial applications. Their services are engineered around downstream business outcomes, specializing in fraud detection data, personalization engines, and customer
Introduction No one likes talking to an automated machine that repeats static texts and dead-end answers. In today’s business environment, leveraging NLP for Conversational AI has evolved basic bots into live, human-like interactive systems. Creating truly human-like AI chatbots requires a blend of advanced Natural Language Processing in chatbots, including intent recognition, entity extraction, and sentiment analysis, powered by high-quality training datasets. In this article, we’ll explore how mastering chatbot NLP techniques allows Conversational AI chatbots to understand context and deliver natural, human-like conversations. What are Conversational AI Chatbots and How Does Natural Language Processing Work with Them? Conversational AI chatbots are software applications designed to simulate real-time interaction. Applying effective chatbot NLP techniques allows Natural Language Processing in chatbots to break down user intent, ensuring human-like AI chatbots deliver accurate answers rather than rigid scripts. At the heart of this intelligence is NLP for Conversational AI, a core branch of AI that gives chatbots the language skills needed to understand, interpret, and respond to human speech. While it might seem like a black box where text goes in and answers magically come out, it actually operates on a sophisticated pipeline that processes every interaction in milliseconds, using Natural Language Understanding (NLU) to break down user input before triggering specific actions. Read Also: Top 10 NLP Providers in 2025 How NLP for Conversational AI Powers Human-like Interactions To break down how human conversation is simulated, NLP techniques operate as an integrated workflow to translate text into actionable meaning: Intent Recognition & NLU: When a customer types into a SaaS platform, (I want to adjust my current subscription to the annual plan), the NLP Engine doesn’t search for abstract keywords. Instead, it analyzes the functional intent (Upgrade/Modify Subscription), regardless of how the customer phrases it. Smart Data Extraction (Entity Extraction / NER): Capturing critical details between the lines, such as product names, account types, or specific dates, to deliver a tailored, direct response without repeatedly asking the user for details they have already mentioned. Sentiment Analysis & Context Awareness: Reading the customer’s tone (whether they are frustrated by a service outage or making a routine query) and retaining full conversation history to prevent repetitive questions and deliver an emotionally appropriate response. By combining conversational AI with these integrated NLP techniques, AI chatbots can analyze user input, extract key details, and assess emotional tone, allowing them to run natural conversations and execute real tasks efficiently. How Training Data Powers Your Chatbot’s NLP Performance Creating effective Conversational AI isn’t a one-time task, it requires continuous refining. To keep your AI chatbot reliable and user-friendly, focus on high-quality data design principles Delivered by professional Text collection services: Build a Rich Dataset: For a bot to accurately recognize what a user wants, it needs a solid amount of training examples. Aiming for around 100 sample phrases per core goal ensures the system learns effectively. Include Diverse Phrasings: People phrase requests differently. Train your model using varied sentence structures, for instance, train a SaaS support bot on both (I want to cancel my subscription) and (Stop my monthly billing). Keep Core Goals Distinct: Avoid using nearly identical phrases for different actions (such as View Invoice versus Pay Invoice), as overlapping language can confuse the AI. Ensure primary business requests (like Upgrade Plan) have a strong volume of examples gathered through Text collection services, preventing the NLP engine from favoring simple greetings over critical tasks. Also Read: Top Data Annotation Providers for Natural Language Processing (NLP) Final Thoughts Building effective NLP for Conversational AI isn’t just about deploying pre-trained models, it requires continuous dataset optimization and precise text annotation. At SO Development, we help you design intelligent conversational systems and prepare the exact datasets needed to power them. From gathering tailored Chatbot Training Datasets to providing high-precision Text Annotation Services, including Named Entity Recognition (NER), Sentiment Analysis, and Intent Classification, we supply the clean, ethically sourced data your models require. Empower your AI with unmatched accuracy and natural interaction capabilities, connect with our AI data experts today to elevate your NLP projects! FAQs Q1: How does an NLP-powered chatbot differ from a traditional rule-based bot? Traditional bots strictly follow decision trees and rigid keyword matches. In contrast, an NLP chatbot leverages artificial intelligence to understand context, recognize synonyms, interpret complex phrases, and handle typos, allowing for natural, free form human conversation. Q2: How much training data is actually required to build an accurate NLP chatbot? To achieve high accuracy, an NLP model typically requires a baseline of 50 to 100 diverse, high-quality sample phrases per intent. However, quality and phrasing variety matter more than raw volume; well-annotated and balanced datasets prevent model bias and improve real-world performance. Q3: Why are Text Annotation and Data Collection critical for Conversational AI? AI models cannot guess intent or context on their own. Services like Named Entity Recognition (NER), Sentiment Analysis, and Intent Classification label raw text so the AI can learn to extract dates, names, product IDs, and emotional tone accurately during live interactions. Q4: Can NLP chatbots understand typos and informal slang? Yes. Through text normalization and preprocessing techniques (such as tokenization and lemmatization), NLP models automatically correct misspellings and map informal slang or localized phrasing to the correct core intent. Q5: Why should businesses invest in custom Chatbot Training Datasets instead of public data? Public datasets lack industry-specific terminology, unique product details, and brand-specific conversational nuances. Custom, ethically sourced datasets ensure your chatbot understands your specific customer base and delivers precise, error-free responses. Visit Our Data Collection Service Visit Now
Introduction Deploying artificial intelligence in medicine requires a precise balance between specialized clinical knowledge and disciplined operational engineering. As regulatory standards tighten and the use of large language models and computer vision expands across healthcare, processing medical AI data requires much more than basic surface labeling. It demands end-to-end data lifecycle management. This approach transforms unstructured medical records, images, and audio into high-quality, reliable, and scalable digital assets aligned with clinical safety standards. Key Pillars of Medical Data Processing 1. High-Context Medical Annotation Preparing training data for advanced medical models requires linking annotation points to full clinical context. This specialized medical AI data annotation includes connecting health records to longitudinal patient histories, treatment backgrounds, and overlapping symptoms. This approach equips algorithms to grasp complex details, improve overall AI data quality, and minimize arbitrary decisions or misdiagnoses made without reviewing the patient’s complete file. Also Read: A Guide to Choose a Data Annotation Partner for Healthcare AI Teams 2. Multi-Tier HITL Quality Control Given the high stakes of medical applications, operations rely on human in the loop AI workflows featuring a multi-tier review process involving medical doctors, healthcare specialists, and certified data analysts. Outputs are reviewed and verified at every stage for clinical consistency, ensuring datasets are free from errors of omission, misinterpretation, or hallucinations before final delivery. 3. RAG-Ready Structuring for Generative AI To support conversational assistants and Retrieval-Augmented Generation (RAG) systems, raw medical records and documents are structured specifically for real-time clinical retrieval. This structural design helps reduce annotation errors and directly limits large language model (LLM) hallucinations and grounds AI recommendations in proven medical evidence. 4. Dataset Bias Mitigation To ensure algorithms perform accurately and fairly across diverse patient populations, medical AI data collection and annotation incorporate demographically and geographically balanced samples. This balance mitigates model bias toward specific regions or demographics, improving output accuracy when models run in real-world clinical environments. Also Read: The Future of Medical AI Data in Autonomous Healthcare Systems 5. Multi-Modal Scalability Large-scale medical projects require handling multiple data modalities simultaneously, such as medical imaging (DICOM), Electronic Health Records (EHR), audio consultations, and clinLarge-scale medical projects require handling multiple data modalities simultaneously, such as medical imaging (DICOM), Electronic Health Records (EHR), audio consultations, and clinical text. Dedicated teams provide the operational capacity needed to manage large volumes of medical AI data while sticking to strict project timelines. 6. Strict Governance & Data Security Data processing follows rigorous security and governance frameworks to protect patient information. Operations include complete Personal Health Information (PHI) de-identification and full compliance with international standards like HIPAA and GDPR . Operational 5-Step Workflow At SO Development, we execute medical data projects through a standardized 5-step operational workflow to maintain strict quality control and deliver consistent clinical outputs: Analysis: Reviewing project medical requirements, establishing annotation guidelines, and assessing data complexity. Planning: Assigning specialized teams, drafting annotation guidelines, and setting clear benchmarks for accuracy and timelines. Implementing: Beginning data processing from data collection and annotation by trained specialists following industry best practices. Quality Control (QC): Performing multi-layer reviews by clinical experts to verify consistency, accuracy, and error-free outputs. Delivery: Exporting datasets in required formats alongside transparency and compliance reports. Final Thoughts Moving medical AI systems from test environments into real clinical practice requires more than raw processing power, it demands training data with clinical depth, completeness, and total consistency. Meeting these rigorous standards is central to how we deliver medical data solutions at SO Development, combining strict HIPAA and GDPR compliance with an adaptable operational framework designed around output accuracy. By providing end-to-end data processing, medical expert validation, and flexible service models tailored to varying project scales, we help healthcare organizations build complex diagnostic and automated tools that operate reliably in real-world environments. Ultimately, this focus on data accuracy supports safer clinical tools, better patient outcomes, and broader access to reliable healthcare solutions globally. Frequently Asked Questions (FAQ) Q1: How do you measure annotation quality and reduce errors in medical datasets? A: Quality is measured through multi-tier validation, inter-annotator agreement metrics, and standard benchmark checks. Combining clinical expert reviews with automated verification scripts helps systematically catch omissions and reduce annotation errors before delivery. Q2: What is human-in-the-loop annotation, and why is it required for medical AI? A: Human in the loop AI annotation involves medical specialists reviewing, validating, and refining AI model inputs and outputs. It is essential in healthcare to ensure clinical accuracy, maintain safety standards, and comply with strict legal governance. Q3: How do high-quality datasets and RAG prevent LLM hallucinations in clinical settings? A: Structuring datasets specifically for Retrieval-Augmented Generation (RAG) forces language models to retrieve verified medical facts from trusted clinical databases rather than guessing, drastically reducing hallucinations. Q4: Can personal health data be used for training medical AI models under GDPR? A: Yes, provided the data undergoes strict Personal Health Information (PHI) de-identification, anonymization, or pseudonymization, and adheres to clear consent frameworks and legal data protection agreements (DPA). Q5: How do you reduce bias in medical training datasets? A: Bias is mitigated during medical AI data collection by sampling balanced, multi-regional datasets that reflect diverse demographics, ethnicities, and clinical conditions to ensure fair model performance. Next Step Do you have a medical AI project that requires high-precision, compliant data solutions? At SO Development we help you structure your project, and offer you a Dataset Assessment to discover how tailored medical AI data solutions can support your model’s accuracy and clinical success. Contact our experts at SO Development today to define your requirements and Dataset Assessment. Visit Our Data Collection Service Visit Now
Introduction With the notable expansion of clinical models, medical AI diagnostic errors have become a critical issue for healthcare providers. A Burns & Wilcox study (2026) confirmed that advanced clinical models can commit between 12 to 15 diagnostic errors per 100 cases with poor data. In fact, 76% of these issues are errors of omission, such as overlooking key risk factors. The problem extends beyond missing details. Algorithms often rely on inaccurate inputs. A study published in Nature (2026) showed that generative AI medical models believed incorrect data in reports 47% of the time. Improving medical AI data quality ensures deep-reasoning models maintain much higher accuracy. In this article, we review what causes medical AI diagnostic errors, how to avoid them, and how technology protects patient safety. What Causes Medical AI Diagnostic Errors in Clinical Settings? According to a study published in PubMed Central (2026) regarding algorithm liability and governance, the main causes of diagnostic errors in medical AI systems are: Poor Data Quality and Diversity: Algorithm accuracy drops directly when trained on incomplete or noisy data, or data lacking demographic and geographic diversity. This causes data bias, resulting in weak decisions for specific populations. Algorithmic Complexity (Model Opacity): When complex data is unexplained or accurately labeled, the model becomes a black box. This prevents doctors from verifying conclusions and leads to model hallucinations. Challenges Across Key Medical Specialties: Medical Image Annotation & Dermatology: Detection accuracy reaches 90-95%, but struggles in atypical cases due to a lack of diversity in training data. Radiology: Lung cancer diagnosis accuracy reaches 85-95%, but is affected by image quality and data noise. Pulmonology: Pneumonia diagnosis accuracy reaches 85-93% in rapid emergency triage, but faces challenges from overlapping symptoms and visual data accuracy. See Also: The Future of Medical AI Data in Autonomous Healthcare Systems How to Prevent Medical AI Diagnostic Errors To ensure the highest levels of safety and clinical effectiveness for smart models, errors can be reduced through the following systematic steps: Relying on RAG in Medical AI for Reliable Data Retrieval: Retrieval-Augmented Generation (RAG in medical AI) connects the language model to trusted clinical databases. This technology prevents models from guessing. It forces the system to extract answers only from high-quality sources. High-Context Data Framing: Using frameworks like SaferDx and SPADE helps teams annotate medical data in full context. This teaches algorithms to catch complex details. (See also: Medical annotation Services) Activating Human-in-the-Loop AI Principles: Healthcare systems should not allow models to issue independent diagnoses. Applying human-in-the-loop AI requires human doctors to review and approve every output, protecting patient safety. (See also: Human-in-the-Loop Services) Automated Completeness Checks: Addressing 76% of omission errors using mandatory check algorithms that automatically match system recommendations with the patient’s medical record to verify no essential tests are missed. Data Pathology Mitigation: Training models on balanced demographic and ethnic data to ensure fairness in diagnosis. Applying Explainable AI (XAI): Developing systems that do not just provide diagnoses, but also explain the clinical reasons and reference texts they relied on. Real-Time Monitoring Dashboards: Monitoring algorithm performance inside hospitals to detect any drop in model accuracy when dealing with a new patient demographic. See Also: A Guide to Choose a Data Annotation Partner for Healthcare AI Teams Final Thoughts Following the previous advice and methods ensures reducing diagnostic errors in smart models to their lowest levels. However, the most important factor is always verifying training data quality from day one. AI cannot produce better results than the data it was built on. Reliable, accurately annotated, and error-free medical data is the only guarantee for a safe, accurate AI system that earns the trust of doctors and patients. At SO Development, we offer high-quality medical training data, providing high-quality medical data annotation accompanied by the highest privacy and encryption standards. All processing and data de-identification operations are conducted under the supervision of top doctors and health specialists to ensure your algorithms excel. Contact our data expert team today to secure training data for your medical AI model! Frequently Asked Questions (FAQ) Q1: Why do diagnostic errors occur in medical AI? A: In most cases, errors stem from input data quality. If training data is incomplete, inaccurate, or biased, the AI will issue wrong results and recommendations based on it. Q2: How does RAG technology help reduce AI errors? A: RAG technology prevents AI from guessing or inventing by forcing it to retrieve information only from accurate, trusted medical databases at the moment of answering. Q3: What is meant by High-Context Data? A: It is medical data that is not annotated superficially, but clarified and linked to the patient’s full medical history, symptoms, and outcomes over time, helping AI understand the case in its full scope. Q4: Can doctors be replaced by AI? A: No. The goal of AI is to act as a clinical assistant that reduces paperwork burden and flags errors (Human-in-the-Loop), while the final decision always remains with the human doctor. References Burns & Wilcox Report (2026): Study: AI Generates Severe Errors in 22% of Medical Cases. https://www.burnsandwilcox.com/insights/study-ai-generates-severe-errors-in-22-of-medical-cases/ Nature Journal Study (2026): Evaluating Misinformation and Deep-Reasoning Models in Generative AI Diagnostics. https://www.nature.com/articles/s41746-026-02547-z PubMed Central (PMC) Comprehensive Study (2026): Data quality, diversity, and accountability in AI diagnostics. https://pmc.ncbi.nlm.nih.gov/articles/PMC12615213/ Visit Our Data Collection Service Visit Now